Process Mining Finds Where Work Really Stalls
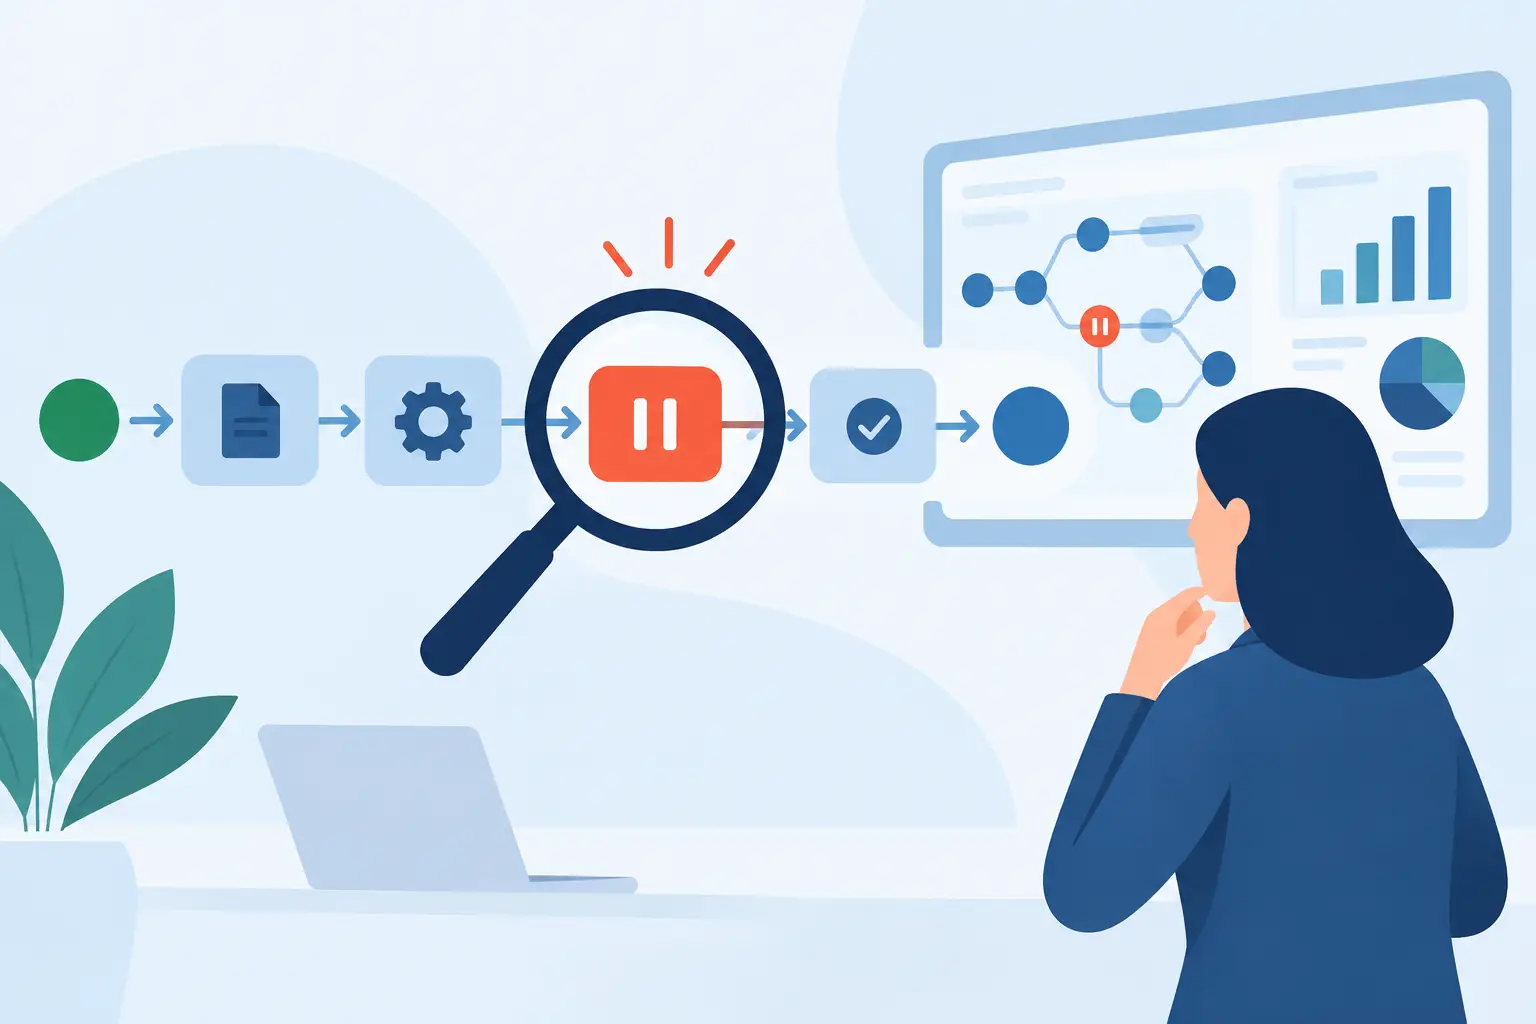
A customer request is entered on Monday, approved on Tuesday, then sits untouched until the following week. The stated process may say it takes two days. Process mining shows what actually happened: where work waited, which handoffs created rework, and why the outcome varied. For leaders considering AI or automation, that distinction can prevent expensive mistakes.
Most organizations already have a trail of operational evidence in their ERP, CRM, service desk, claims platform, ticketing system, or case-management software. The challenge is that the evidence is fragmented across tools and rarely examined as a complete process. Teams rely on workshops, written procedures, and individual experience. Those sources matter, but they describe intended work. They do not consistently reveal real work at scale.
What process mining does differently
Process mining reconstructs business processes from the digital event logs created when people and systems do their work. Each event needs a case identifier, an activity, and a timestamp. For example, a purchase order number might be the case, while “request created,” “manager approved,” “vendor updated,” and “invoice matched” are activities.
The resulting analysis maps the actual paths work takes through the organization. It can show that 60 percent of requests follow the expected route while the rest are sent back for missing information, redirected to another team, or approved outside the normal sequence. It can also measure cycle time, queue time, repeat work, exceptions, and process variations.
That makes it more useful than a static flowchart. A flowchart is a design document. Process mining is operational evidence.
This does not make interviews or frontline knowledge less valuable. It gives those conversations a stronger starting point. When a process map shows an approval queue growing every Friday, leaders can ask the relevant question: is capacity too low, are requests arriving incomplete, is a policy creating unnecessary checks, or is the system routing work poorly?
Where process mining creates business value
The strongest use cases have three characteristics: a high volume of transactions, meaningful process data, and a measurable business consequence when work is slow or inconsistent. Order-to-cash, procure-to-pay, customer onboarding, claims handling, incident management, employee onboarding, and service delivery are common candidates.
In a logistics operation, the issue may be delayed dispatches caused by late exception handling. In financial services, it may be applications moving through too many manual review loops. In a professional services firm, it may be client intake work that begins in email, gets re-entered into multiple tools, and reaches the delivery team without essential information.
The value is rarely limited to speed. Process mining can identify compliance risks, such as cases completed without a required approval, as well as customer experience problems and workload imbalances. It can reveal where skilled employees are spending time chasing status updates or correcting preventable errors rather than applying judgment to complex work.
For Canadian organizations handling sensitive data, the method also supports more disciplined decision-making. Rather than moving records into a new AI tool because it appears promising, leaders can identify the smallest, highest-value intervention and define the access controls, retention rules, audit requirements, and human review points before deployment.
Process mining is not an automation project by itself
A process map can be compelling, but visibility alone does not improve an operation. The practical question is what to change after the analysis.
Sometimes the answer is not AI. A confusing intake form, duplicate approval, outdated policy, or poor system configuration may be the real constraint. Fixing it may be faster and less costly than building an agent or automation around it. This is a useful outcome, not a disappointing one. It stops an organization from automating waste.
Other findings point to well-bounded opportunities for technology. If employees repeatedly extract the same details from documents, an AI-assisted intake workflow may help. If a team manually triages routine requests by clear rules, workflow automation could route them immediately. If the work requires interpretation, an AI agent may prepare a recommendation while a qualified employee makes the final decision.
The trade-off depends on risk and variation. Highly standardized, low-risk work is often a good candidate for straight-through automation. Work involving regulated decisions, confidential client information, or ambiguous exceptions needs stronger controls and human approval. The goal is not to remove people from every process. It is to remove repetitive friction while preserving accountability.
The data requirements leaders should understand
Process mining is often described as a software problem. In practice, data readiness is the first test. Event data must be sufficiently reliable to connect activities to the same case and place them in a meaningful sequence.
A useful initial review examines where the process starts and ends, which systems record key events, whether timestamps are trustworthy, and how cases are identified across platforms. Data does not need to be perfect to begin, but the limitations need to be explicit. If a key handoff happens through informal email or a spreadsheet outside the main system, the map may understate that work unless those signals are included.
Privacy and security belong in this early stage. Organizations should apply data minimization, role-based access, secure environments, and clear rules for handling personal or confidential information. For Canadian businesses, that also means considering PIPEDA obligations, provincial requirements where applicable, contractual commitments, and whether data residency is a condition of the engagement.
A credible process mining initiative does not require broad access to every system. Start with the events needed to answer a defined operational question. This reduces risk, speeds analysis, and makes it easier to validate findings with the people who run the process.
From evidence to deployment: Discover, Build, Adapt
The best path is focused rather than theoretical. Start by selecting one process tied to a commercial or operational outcome: reduced turnaround time, fewer touches per case, fewer compliance exceptions, better service levels, or improved capacity. A vague objective such as “use AI more” is too broad to guide the work.
Discover the real process
In the discovery stage, combine process mining data with stakeholder interviews and a review of systems, policies, and controls. The purpose is to separate symptoms from causes. A long cycle time, for instance, may come from a small number of cases that wait for customer information, not from the core approval activity itself.
Prioritize opportunities by value, feasibility, data quality, implementation effort, and risk. This is where organizations avoid tool overload. A process issue does not automatically require a new platform. It may call for a workflow adjustment, integration, targeted automation, or a carefully scoped AI capability.
Build the intervention, not another presentation
The build stage turns the selected opportunity into working software and an operational workflow. That can include an AI agent, document-processing capability, system integration, automated routing, or a management dashboard that flags cases at risk of breaching service levels.
Design decisions should reflect the process evidence. Define what the tool can do independently, where it must request approval, how exceptions are escalated, and what information it can access. Test against real-world variations, not only the cleanest cases. A solution that works only when every field is complete and every customer behaves predictably will fail where teams need it most.
Adapt with measurement and ownership
Deployment is the beginning of operational learning, not the finish line. Measure the same indicators that justified the work: cycle time, rework, backlog, exception rate, employee effort, and customer outcomes. Compare performance before and after implementation, then adjust the workflow as patterns change.
This is also the point to clarify ownership. Operations leaders own the business result. IT and security teams govern integration and access. Frontline employees identify edge cases and adoption barriers. A capable implementation partner should support each group while remaining accountable for a deployed solution, not just a recommendation deck.
Common mistakes that limit results
The first mistake is treating process mining as a one-time diagnostic exercise. Processes evolve when policies, staffing, demand, systems, and customer expectations change. Rechecking critical workflows can identify drift before it becomes a service or compliance problem.
The second is choosing a process because it is easy to access rather than because it matters. A clean dataset is useful, but a low-value process will not build momentum for broader adoption. Start where better flow would materially affect revenue, cost, risk, capacity, or customer experience.
The third is assuming every variation is a defect. Some variations reflect legitimate expertise, client needs, or regulatory obligations. The task is to distinguish necessary judgment from avoidable inconsistency. That is why data analysis must be reviewed with the people closest to the work.
Process mining gives leaders a practical way to move from assumptions to evidence. Before choosing an AI tool, ask a simpler question: where does work actually slow down, and what would make that work better for employees, customers, and the business? The answer is often the most useful place to begin.